
Since August 2026 the text you get from the biggest AI assistants is no longer just text. Claude and Gemini now hide a statistical watermark in the words they choose, and OpenAI has said text is next for ChatGPT. You cannot see it, but the provider can check for it, and so can anyone they hand a detector to. If you build websites, write for clients or publish at scale, here is what is inside AI-generated text today, how to check your own content, how to remove AI watermarks, and how to generate clean text with the NoTrack API in the first place.
The Invisible Label on Your Content
On August 2, 2026 the transparency rules of the EU AI Act (Article 50) started to apply. They require providers of generative AI to mark what their systems produce in a machine-readable way, so it can be detected as AI-generated. The big labs moved fast.
- Anthropic (Claude). On August 14, 2026 Anthropic announced that new Claude models generate text that contains a watermark, with older models being updated over the following months. A detection API is already in private preview for regulators, law enforcement, media, fact-checkers, researchers and educational organizations.
- Google (Gemini). Gemini has watermarked its text output since 2024 with SynthID, a method Google DeepMind published in Nature and open-sourced in 2024. Claude's watermark is built on the same approach.
- OpenAI (ChatGPT). OpenAI already marks generated images and audio and has said it wants to extend content provenance to text. It has reportedly built a text watermark internally but not shipped it yet.
For a casual user asking for a recipe, none of this matters. For anyone who publishes AI-assisted text, sells it, or delivers it to clients, it changes the game: your content now carries a signature that you did not add, cannot see and cannot turn off.
Two Kinds of AI Text Watermark
"AI watermark" gets used for two very different things. Knowing which one you are dealing with decides how you remove it.
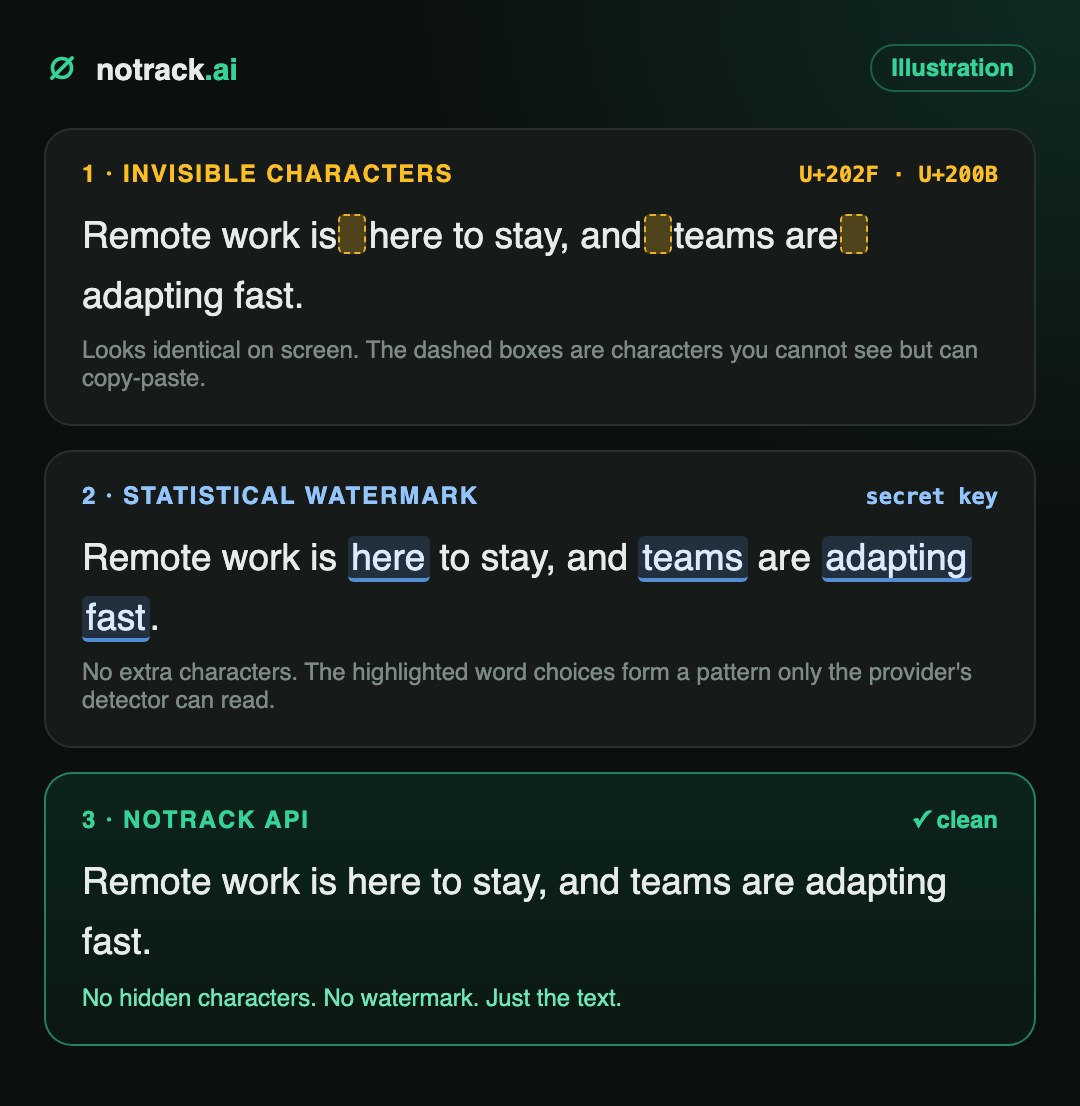
Invisible characters
Unicode characters that look exactly like a normal space or like nothing at all: zero-width spaces, word joiners, narrow no-break spaces.
- Easy to detect with a simple script
- Easy to remove: strip or replace them
- Break things quietly: search, word counts, keyword matching, code
Statistical watermarks
No extra characters at all. The model's word choices are steered by a secret key, leaving a pattern only the provider's detector can read.
- Invisible to readers and to any text editor
- Survives copy-paste and light editing
- Weakens with heavy rewriting; a complete rewrite removes it
Invisible characters: the ChatGPT episode
In April 2025, researchers noticed that text from OpenAI's then-new o3 and o4-mini models contained narrow no-break spaces (U+202F) in places where a normal space belonged. Pasted into Word with formatting marks switched on, they showed up as tiny circles instead of dots. OpenAI said the characters were a quirk of large-scale reinforcement learning, not a deliberate watermark, and the characters later stopped appearing. The lesson stuck anyway: AI text can carry characters you never see, and they travel with every copy-paste into your CMS.
Statistical watermarks: SynthID and Claude
A language model picks every next word from a list of likely candidates, with a bit of randomness. A statistical watermark replaces that randomness with a pseudo-random choice seeded by a secret key. To a reader the text looks completely normal. To someone holding the key, a long enough passage shows a pattern of word choices that would almost never happen by chance.
The words that Claude picks are still random, but now, one can check the sequence of words and see if it's consistent with the choices Claude would make if it was using the key.
Anthropic, How Claude's text watermarking works (August 2026)
Two details matter for publishers. The watermark gets stronger the longer the text is, and according to Anthropic, light editing will not remove it, while a complete rewrite where every word is replaced will.
Who Watermarks AI Text (September 2026)
| Provider | Text watermark | Type | Who can check it |
|---|---|---|---|
| Google Gemini | Yes, since 2024 | Statistical (SynthID) | Google's SynthID tools |
| Anthropic Claude | Yes, new models since August 2026 | Statistical (SynthID-based) | Anthropic detection API, private preview for regulators, media, educators and researchers |
| OpenAI ChatGPT | Not on text yet; images and audio already marked | Text provenance announced as a goal | OpenAI tools (images and audio today) |
| NoTrack API | No | No watermark, no hidden characters | Nobody |
Why Watermarked Text Hurts Content Creators
Google has said for years that it ranks content on quality, not on how it was produced. The problem is everyone else in the chain.
- Your clients can check. Agencies and freelancers deliver text to people who increasingly run AI checks before they pay. A watermark turns "AI-assisted and carefully edited" into "flagged" with no room for nuance.
- Platforms and marketplaces screen. Publishing platforms, freelance marketplaces, ad networks and review sites are adding AI detection. A detectable signature is the easiest thing in the world to filter on.
- It reveals your workflow. A watermark tells anyone with a detector which tool wrote your content. For a content business, that is competitive information you never agreed to publish.
- It follows the text everywhere. Syndicated, translated lightly or reposted, watermarked text keeps its signature. You cannot audit what you cannot see.
- Hidden characters break things. Invisible Unicode quietly breaks on-site search, exact-match keywords, word counts, spell checkers and any code you paste. It can also make two identical-looking pages differ byte for byte.
How to Check Your Text for AI Watermarks
1. Invisible characters: check in seconds
Quick manual test: paste the text into Microsoft Word and press Ctrl+Shift+8 (Cmd+8 on Mac) to show formatting marks. Normal spaces appear as dots; special spaces appear as small circles or other symbols. For anything at scale, use a script:
import unicodedata

SUSPECT = {0x00A0, 0x202F, 0x2007, 0x2009, 0x200A, 0x205F, 0x3000,
           0x200B, 0x200C, 0x200D, 0x2060, 0xFEFF, 0x00AD}

def find_hidden(text: str):
    hits = []
    for i, ch in enumerate(text):
        if ord(ch) in SUSPECT or unicodedata.category(ch) == "Cf":
            hits.append((i, f"U+{ord(ch):04X}", unicodedata.name(ch, "?")))
    return hits

print(find_hidden(open("article.txt", encoding="utf-8").read()))
One caveat worth knowing: the zero-width joiner (U+200D) is also a legitimate part of many emoji, such as 🚴♂️. If a hit sits inside an emoji, leave it alone.
2. Statistical watermarks: you cannot check them yourself
There is nothing to see in the text. Only the provider's detector, which holds the secret key, can tell whether a passage is watermarked. Anthropic's detection API is in private preview for selected organizations, not for the public. In practice that means you have to assume: if a watermarking model wrote it and you did not fully rewrite it, it is marked.
How to Remove AI Watermarks from Text
- Strip invisible characters. Replace special spaces with normal spaces and delete zero-width characters. Safe, instant and lossless.
- Rewrite completely with an independent model. Light edits leave a statistical watermark intact. A full rewrite, where sentence structure and word choice change throughout, does not. Use a model that does not watermark its own output, otherwise you just swap one signature for another.
- Humanize the style. A full rewrite plus the humanizer prompt from our guide to humanizing AI text removes the stock phrases and flat rhythm detectors love.
- Scan once more. Run the character check again before you publish. It takes a second.
Step 1 in code: clean the characters
import re

SPACES = r"[\u00A0\u202F\u2007\u2009\u200A\u205F\u3000]"
ZERO_WIDTH = r"[\u200B\u200C\u2060\uFEFF\u00AD]"

def clean(text: str) -> str:
    text = re.sub(SPACES, " ", text)
    return re.sub(ZERO_WIDTH, "", text)
Step 2 in code: a full rewrite through NoTrack API
from openai import OpenAI

client = OpenAI(base_url="https://api.notrack.ai/v1", api_key="sk-notrack-...")

REWRITE = ("Rewrite the user's text from scratch in your own words, the way a sharp "
           "human writer would say it to a friend. New sentence structure and new word "
           "choice everywhere, same meaning and every fact kept. Plain everyday words, "
           "contractions, short and long sentences mixed. No em dashes. "
           "Output only the rewrite.")

def rewrite(text: str) -> str:
    r = client.chat.completions.create(
        model="notrack-uncensored",
        temperature=0.9,
        messages=[{"role": "system", "content": REWRITE},
                  {"role": "user", "content": clean(text)}],
    )
    return r.choices[0].message.content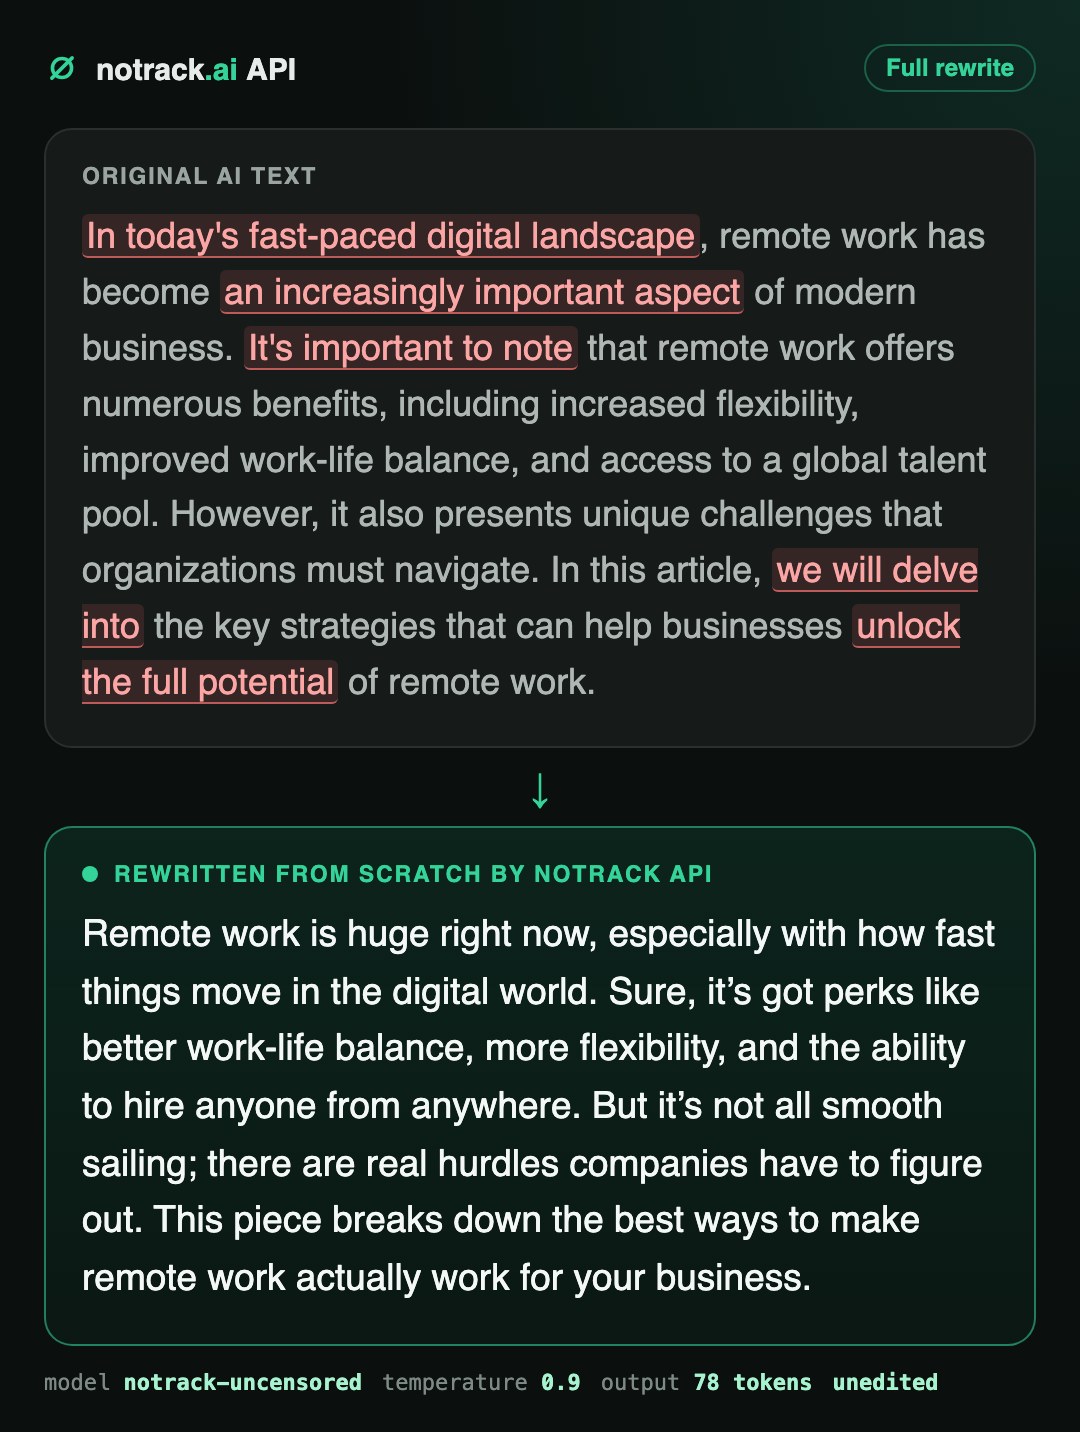
Rewrite long documents section by section. It keeps quality high and makes sure every part of the text is rewritten, not just the opening.
Or Skip the Watermark Entirely
Cleaning text after the fact works. Not having anything to clean works better. NoTrack API runs our own uncensored model on our own GPUs. It is not a wrapper around OpenAI, Anthropic or Google, so no upstream provider stamps its signature on your text on the way through.
- No watermark. NoTrack output carries no statistical watermark and no provenance signature. The text is yours, nothing else is attached to it.
- No hidden characters, measured. We scanned 26 NoTrack API responses, about 20,000 characters, for zero-width and special space characters. Outside of one emoji, the count was zero.
- No logs. Prompts and replies are never written to disk, not by the gateway and not by the model servers. We keep a request ID and token counts for billing. Nobody can look your content up later.
- No topic filter. Nightlife, dating, adult, gambling, crypto, dark fiction: the model writes and rewrites what mainstream assistants refuse or water down.
- Two-line switch. OpenAI-compatible. Change the base URL to
https://api.notrack.ai/v1and the key, keep the rest of your code, tools and plugins.
from openai import OpenAI

client = OpenAI(base_url="https://api.notrack.ai/v1", api_key="sk-notrack-...")

article = client.chat.completions.create(
    model="notrack-uncensored",
    messages=[{"role": "user", "content": "Write a 600-word guide to choosing trail running shoes."}],
).choices[0].message.content

# Clean from the start: no watermark to remove, no hidden characters to strip.
print(article)
Writing 1,000 articles of 800 words costs roughly $1.10 in output tokens. The free credit on your first key is enough to test the whole workflow before you spend a cent. Create your key or read the API docs.
FAQ
Does ChatGPT watermark its text?
Not as of September 2026. OpenAI marks generated images and audio and has said it wants to extend provenance to text. In April 2025 some ChatGPT models produced invisible narrow no-break spaces, which OpenAI described as a training quirk rather than a watermark.
Does Claude watermark its text?
Yes. Anthropic announced in August 2026 that new Claude models generate watermarked text, using a statistical method based on Google's SynthID, and that older models are being updated. The watermark adds no characters; it lives in the word choices.
Does Gemini watermark its text?
Yes. Google has watermarked Gemini's text output with SynthID since 2024.
Can I remove a watermark by editing a few words?
No. Statistical watermarks survive light editing. Anthropic itself notes that a complete rewrite where every word is replaced removes the watermark. Rewrite fully with a model that does not add its own watermark.
What is a ChatGPT or Claude watermark remover?
It is a two-step process: strip invisible characters, then rewrite the text completely with an independent model. The Python snippets above do both, using NoTrack API for the rewrite.
Does NoTrack API add a watermark or hidden characters?
No. NoTrack runs its own model on its own hardware and adds no watermark, no provenance signature and no hidden characters. It also does not store your prompts or outputs.
Does Google penalize AI-generated content?
Google has said it rewards helpful, high-quality content however it is produced. Watermarks matter less for ranking and more for the people and platforms you deliver content to.